
 Add as a preferred source on Google
Most Qwen3-32B Neuron Response Poles Have One Main Function, Researcher Estimates
Cammarata’s preliminary tally puts about 7% of poles in a two-function group and leaves 2% to 4% unexplained; he says the results depend on thresholds and definitions.

Nick Cammarata, a Goodfire researcher and co-author of OpenAI’s 2023 neuron-interpretability paper, estimates that about 90% of Qwen3-32B’s neuron response poles serve one main function. The preliminary finding challenges the view that model internals are broadly tangled.
His breakdown assigns about 7% of poles to two related functions, while 2% to 4% remain unexplained. A response pole represents either the positive or negative direction of a neuron’s activity. Cammarata cautioned that the share changes with the cutoff for weak activations, the model layers examined and the definition of a single function. He described the figures as a working hypothesis in an Oct. 15 essay.
Mechanistic interpretability studies how a model’s internal components and circuits contribute to its behavior. Cammarata offers “recursive generalization” as a possible explanation for neurons that appear to combine concepts: He suggests learning can add connected variants to a neuron’s role over time. The idea pushes back on treating every mixed activation as proof that a model’s concepts are inseparable. Cammarata argues researchers may be able to inspect a model’s neurons directly, without first building another model to break apart its internal representations.
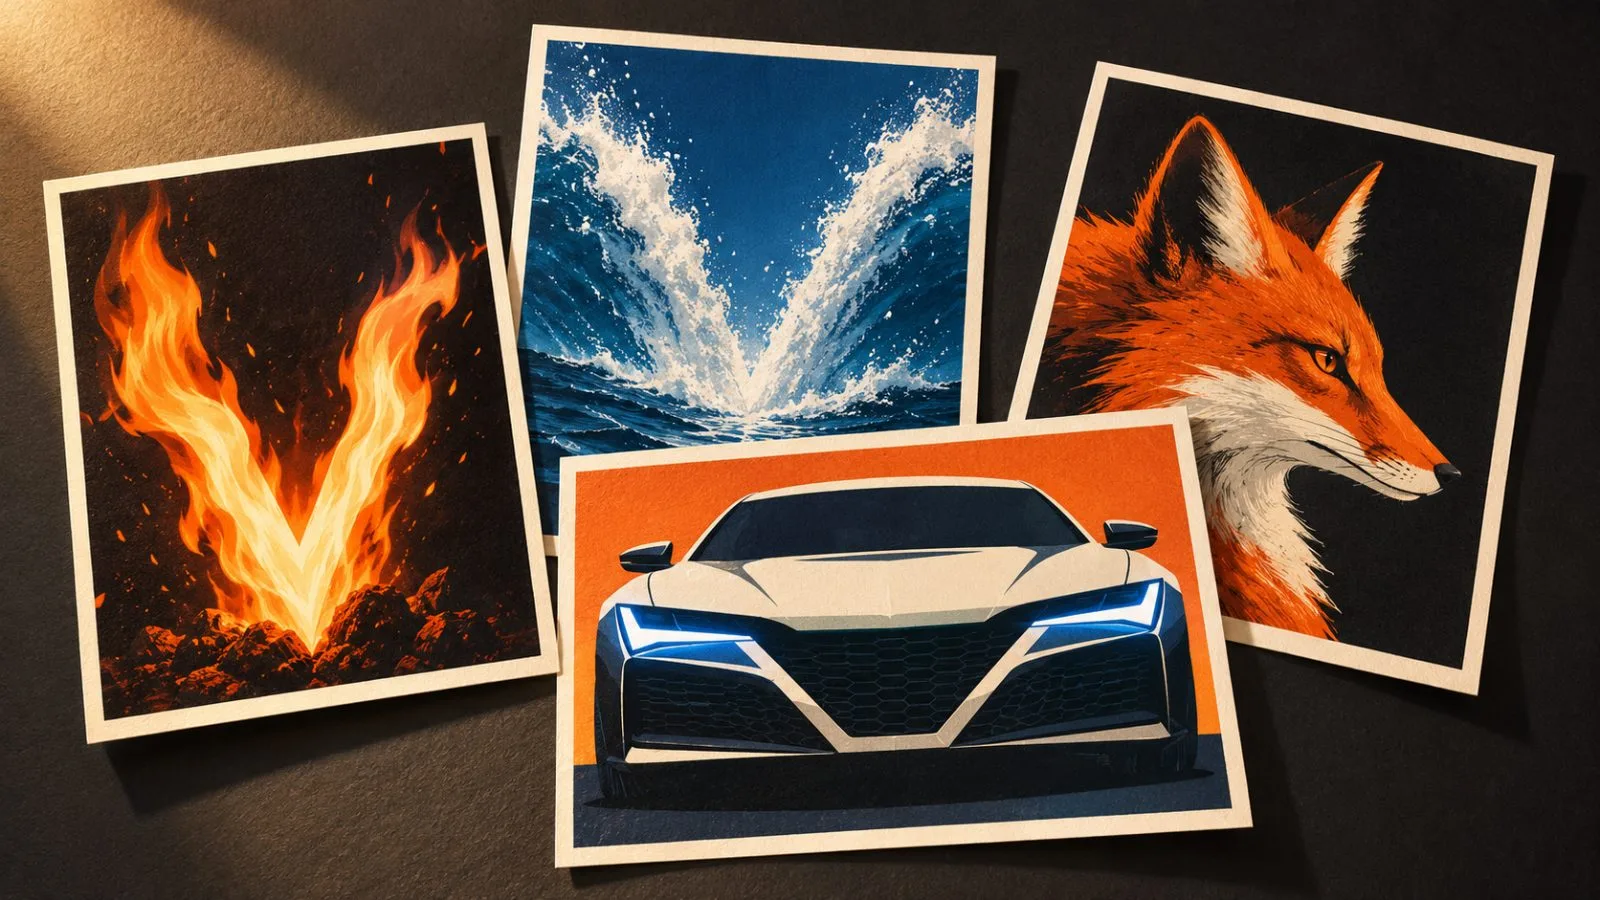
To illustrate, he revisits an InceptionV1 vision-model neuron previously linked to cat faces and car fronts. Cammarata now interprets its activity as a response to a shared V-shaped pattern, also visible in flames, water jets and fox faces.
Cammarata recalled that an OpenAI project examining GPT-2 XL found about 1.7% of neurons interpretable under its most generous measure. That figure is his retrospective account and is not a direct comparison with Qwen3-32B: The projects used different models and analyses.
He also says he and colleagues observed similar patterns in models with as many as trillions of parameters, including Kimi K3. A technical paper covering the language-model results is still forthcoming.
Neel Nanda, Google DeepMind’s mechanistic interpretability lead, called the work interesting but said, “I don't think it's a significant update to the big picture of interpretability.” Cammarata argues improved access to model mechanisms could support alignment research, but the Qwen3-32B audit does not establish that the model is safe or aligned.
Simon Yoon
ReporterSimon Yoon reports on blockchain technology for TokenPost. Send corrections or tips to info@tokenpost.com.